Spark-0 Scaling Spatially Aligned Tactile Pretraining for Robot Dexterous Manipulation
Teaching vision where contact happens, and actions how it feels.
*Equal contribution §Project leads †Corresponding authors
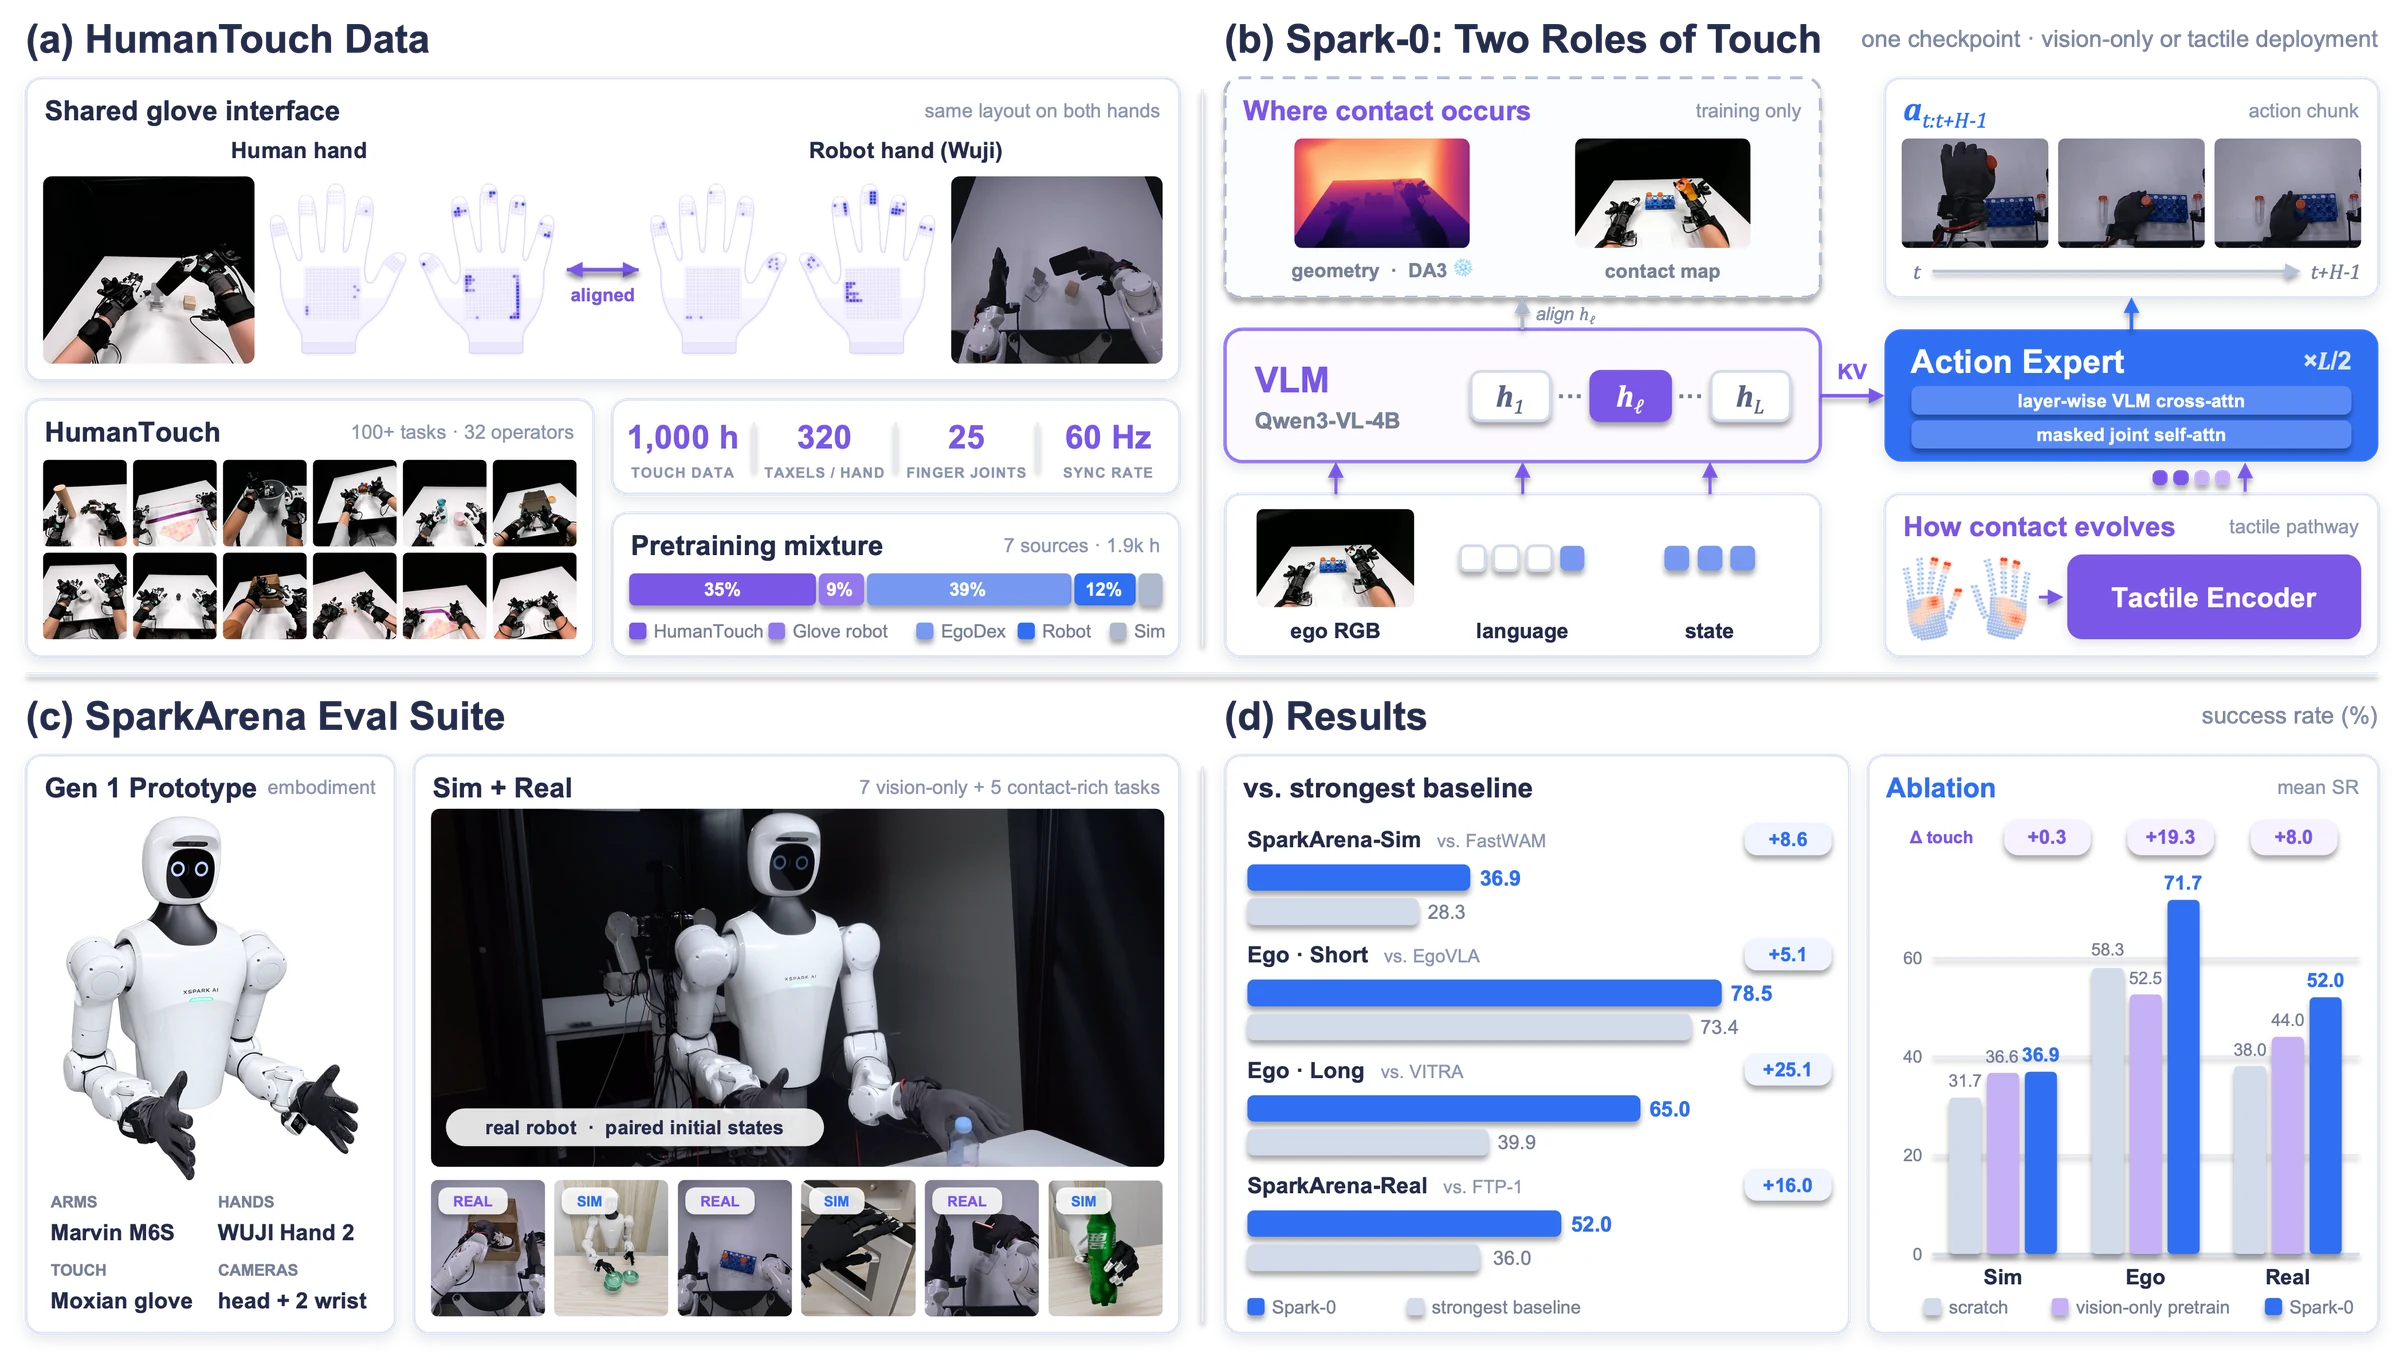
Generalist robot policies benefit from large-scale visual pretraining but often struggle with contact-rich dexterous manipulation, where force, compliance, and incipient slip are hard to observe from images. We present Spark-0, a spatially aligned vision-tactile-language-action (VTLA) model that uses touch in two complementary ways. Image-space contact maps, together with a frozen 3D geometry teacher, supervise the visual tokens on where contact occurs and are removed at inference. In parallel, a tactile pathway encodes regional force histories and 3D taxel states to condition the action expert on how contact evolves. A single checkpoint therefore supports both vision-only and tactile-conditioned deployment. To scale this supervision, we build HumanTouch, 1,000 hours of full-hand tactile human manipulation, and release SparkArena, which pairs vision-only simulated tasks with tactile-conditioned real-robot tasks on one dexterous embodiment.
HumanTouch: 1,000 hours of full-hand touch.
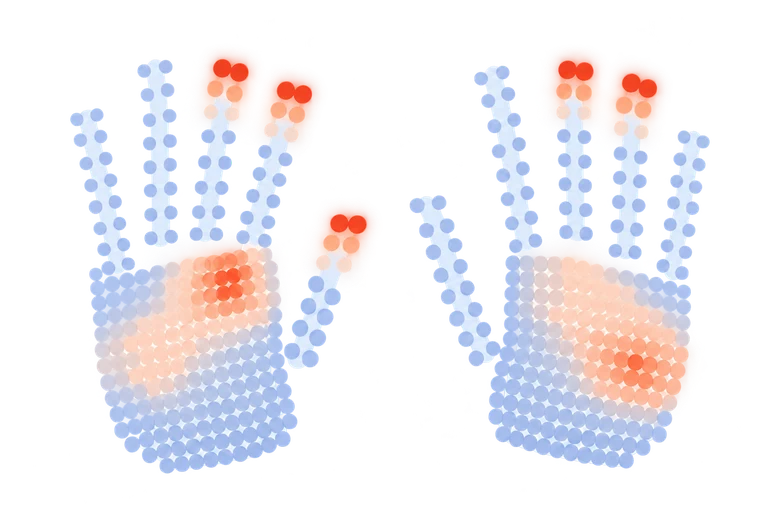
Robot teleoperation is costly and covers a narrow range of contacts, so HumanTouch records humans: more than 100 tasks by 32 operators, with bilateral full-hand tactile gloves, 25-joint finger and 6-DoF wrist tracking, and head and wrist cameras synchronized at 60 Hz. The same gloves mount on the robot hand, giving human and robot data a shared tactile layout.
1,000 hhuman manipulation
100+tasks · 32 operators
320observed taxels / hand
60 Hzsynced RGB · pose · touch
Pretraining mixture
7 sources · 1.9k htouch in 44% of samples
- HumanTouch
- EgoDex
- Same-glove robot
- Robot, tactile removed
- Simulation
- Fourier ActionNet
- AgiBot World
Capture rig same gloves on human and robot hands
(a) Hardware setup
wearable capture rig
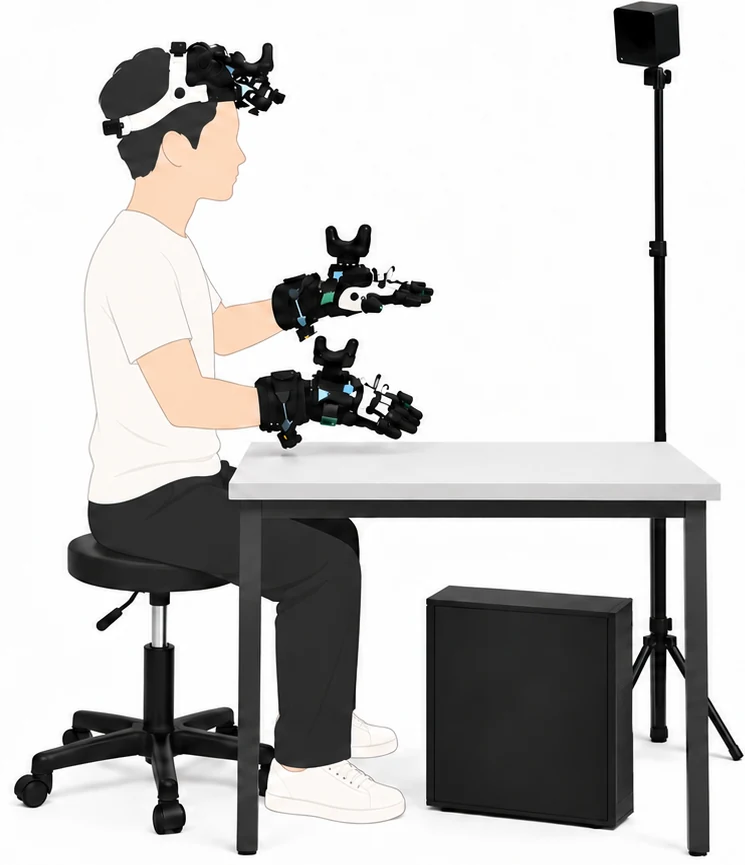
Head camera
HTC VIVE tracker
Wrist cameras
Base station
(b) Synchronized observations
head + dual wrist RGB · bimanual tactile · t = 3 s
Head
Left wrist
Right wrist
Left tactile
Right tactile
(c) Motion capture
outer glove · hand pose
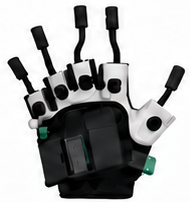
Manus Metagloves
Outer glove
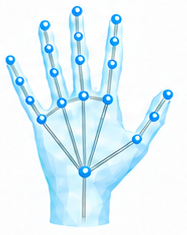
Finger kinematics
3D reconstruction
(d) Tactile sensing
inner glove · contact force
Moxian Gloves
Inner glove
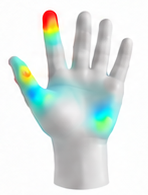
Pressure mapping
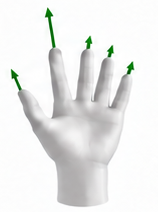
Calibrated force
Where contact occurs, and how it evolves.
Contact-rich control needs two kinds of information that vision provides poorly: where contact occurs, and how it evolves. Spark-0 addresses them separately. Raw touch never enters the VLM, so one checkpoint serves both vision-only and tactile-conditioned deployment.
Backbone a, b
Layerwise VLA
Qwen3-VL-4B conditions a 36-layer flow-matching action expert layer by layer: even layers cross-attend to the VLM; odd layers self-attend over State, Tactile, and Action tokens.
Where · train only a
Spatial alignment
A frozen Depth-Anything-3 teacher and image-space contact maps supervise VLM layer 25. Both heads are discarded at inference, so the gain needs no tactile sensor.
How · runtime c, d
Tactile fusion
24 regional-force and 3D-taxel tokens join the action stream. An asymmetric bias and a training shortcut keep the policy from ignoring touch.
aSpark-0 overview
hover the blocksVisual Supervision
training only
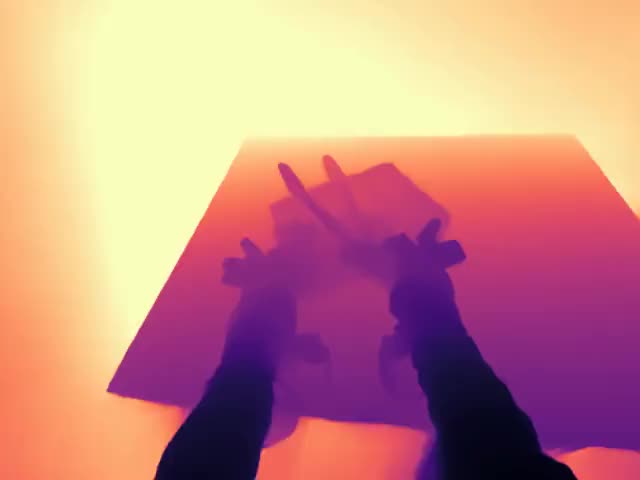
RGB → DA3
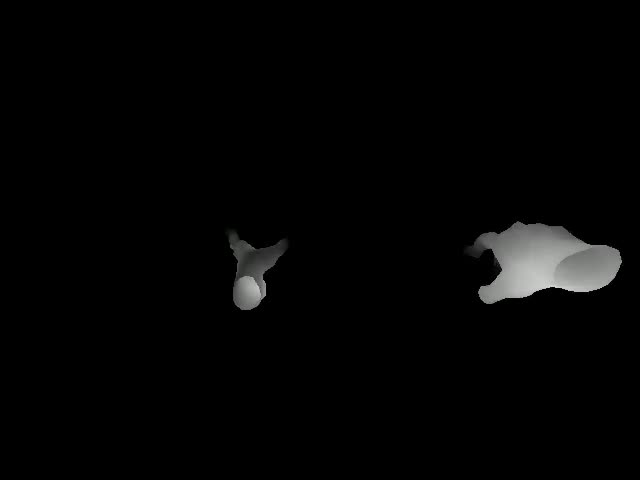
Contact Map
Geometry (all views) + contact map (head) → h25
h1
···
hℓ
···
hL
VLM
Qwen3-VL
layer-wise
KV
KV
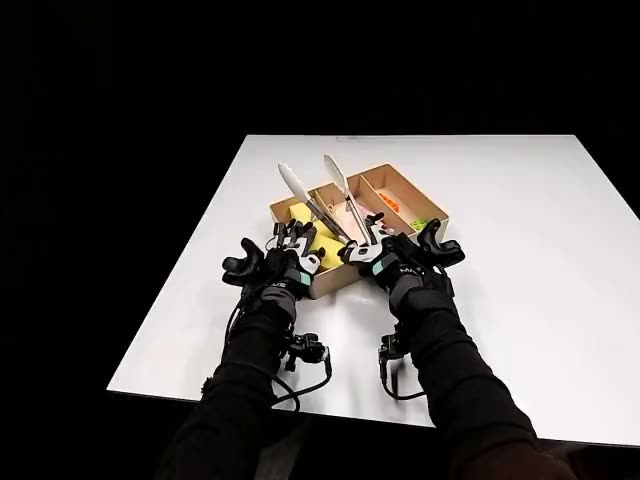
Images
Language
+ discretized state
Action queries
State × 3
Tactile × 24
Action × 50
Joint-Stream DiT· Self
Joint-Stream DiT· Cross
× L/2
at:t+H−1
st−2:t
Tactile Encoder
aτ
bAlternating DiT layers
cross first · L layersState
Tactile
Action
Even layers · i = 0, 2, 4, …
K, V ← hi+1 (VLM + queries)
AdaLN(c)
VLM Cross-Attention
+ x
Odd layers · i = 1, 3, 5, …
Q, K, V : joint sequence
AdaLN(c)
Masked Joint Self-Attention
+ x
Repeat cross → self across L layers
c = Embed(τ) + Embed(flatten(Fl, Fr))
Same conditioning for State · Tactile · Action
cTactile encoder
two hands · region force + 3D taxels3D Taxels
Left
Right
xyz + pressure
pressure
Independent hands · shared MLP / Pool
Point MLPFourier xyz + p
Region Poolsoftmax per region
+ eh + erconcat hands
× γ3Dscalar
3D tokens
Region force · L/R × 6 regions × 20 frames
Log-scaled window → flatten (no conv) → c in (b)
Temporal Conv
+ eh + erconcat hands
× γFscalar
Force tokens
tactile
tokens
tokens
absent → e∅shared placeholder
dAttention mask
hover a cell or the legendQ \ K
VLM
State
Force
3D
Action
State
Force
3D
Action
b(g)
b(g)
b(g)
b(g)
visible
attn bias
b(g) = −6(1−σ(g))
g: tactile-query gate
shortcut
cross
joint self-attention
One HumanTouch episode, played in sync. Raw touch never enters the VLM; it conditions only the action expert.
SparkArena: one robot, two questions.
Because Spark-0 uses touch in two ways, evaluation must ask both: does tactile pretraining improve the visual policy when touch is absent, and does online touch improve contact-rich control? Both tracks run on the same Gen 1 Prototype robot. All assets are released.
7
SparkArena-Sim
Seven vision-only tasks. Does tactile pretraining improve the visual policy when touch is absent?
5
SparkArena-Real
Five tactile-conditioned tasks from paired initial states. Does online touch improve contact-rich control?
- Embodiment
- Gen 1 Prototype, 58-d state and action
- Arms
- 2 × Marvin M6S CCS-696
- Hands
- 2 × WUJI Hand 2, 20 DoF
- Cameras
- Orbbec 336 head · 2 × Orbbec 305 wrist
- Touch
- Moxian gloves, HumanTouch layout
- Metrics
- Success rate · completion score over subgoals
Highest mean success on all three evaluations.
Spark-0 is deployed without touch on SparkArena-Sim and Ego Humanoid, and with touch on SparkArena-Real, against 13 baselines. No evaluated task appears in pretraining.
SparkArena-Sim Results
Without touch, Spark-0 reaches 36.86% success, 8.57 points above FastWAM, and is best on four of seven tasks. Large multi-robot pretraining alone is not enough for high-DoF dexterous control (GR00T-N1.7 14.00%, RDT-1B 9.71%).
Success rate (%) / completion score. Highlight: best; bold: second.
| Method | Click Mouse |
Collect Objects |
Dual Bottles Pick |
Hammer Beat |
Put Food in Microwave |
Retrieve Gap |
Stack Bowls |
Mean |
|---|---|---|---|---|---|---|---|---|
| FastWAM | 28.0028.00 | 8.0024.80 | 40.0052.60 | 58.0058.00 | 32.0032.00 | 2.002.00 | 30.0037.20 | 28.2933.51 |
| VITRA | 14.0014.00 | 6.0017.50 | 62.0071.00 | 46.0046.00 | 32.0032.00 | 2.002.00 | 24.0028.80 | 26.5730.19 |
| StarVLA | 16.0016.00 | 8.0017.80 | 36.0048.60 | 50.0050.00 | 44.0044.00 | 8.008.00 | 22.0027.70 | 26.2930.30 |
| π0.5 | 14.0014.00 | 10.0026.60 | 32.0050.00 | 48.0048.00 | 38.0038.00 | 2.002.00 | 38.0043.70 | 26.0031.76 |
| H-RDT | 30.0030.00 | 6.0013.20 | 28.0039.40 | 52.0052.00 | 48.0048.00 | 0.000.00 | 10.0012.40 | 24.8627.86 |
| UniT | 10.0010.00 | 2.0010.20 | 14.0027.20 | 42.0042.00 | 40.0040.00 | 0.000.00 | 8.0015.20 | 16.5720.66 |
| ACT | 22.0022.00 | 0.005.90 | 2.009.20 | 22.0022.00 | 52.0052.00 | 0.000.00 | 2.004.70 | 14.2916.54 |
| GR00T-N1.7 | 6.006.00 | 2.0010.70 | 34.0047.80 | 34.0034.00 | 20.0020.00 | 0.000.00 | 2.007.40 | 14.0017.99 |
| RLDX-1 | 4.004.00 | 0.0013.90 | 28.0043.00 | 26.0026.00 | 18.0018.00 | 0.000.00 | 10.0011.80 | 12.2916.67 |
| RDT-1B | 4.004.00 | 0.006.10 | 6.0016.20 | 26.0026.00 | 32.0032.00 | 0.000.00 | 0.003.30 | 9.7112.51 |
| EgoVLA | 0.000.00 | 0.004.60 | 8.0014.60 | 14.0014.00 | 16.0016.00 | 0.000.00 | 0.001.20 | 5.437.20 |
| Spark-0 | 42.0042.00 | 8.0014.10 | 62.0070.40 | 52.0052.00 | 52.0052.00 | 10.0010.00 | 32.0037.70 | 36.8639.74 |
Hammer Beat
Stack Bowls
Put Food in Microwave
Dual Bottles Pick
Retrieve Gap
Collect Objects
Ego Humanoid Manipulation Benchmark
First on all eight metrics on an unseen embodiment, without touch at test time. The success margin grows from +3.17 / +6.86 on short-horizon tasks to +18.52 / +22.12 on long-horizon tasks (seen / unseen).
Mean success rate (SR) and partial success rate (PSR). Highlight: best; bold: second.
| Method | Short horizon | Long horizon | ||||||
|---|---|---|---|---|---|---|---|---|
| Seen | Unseen | Seen | Unseen | |||||
| SR | PSR | SR | PSR | SR | PSR | SR | PSR | |
| EgoVLA | 77.78 | 84.92 | 69.11 | 76.26 | 45.93 | 80.78 | 28.79 | 69.11 |
| FastWAM | 72.49 | 83.25 | 32.47 | 45.42 | 49.63 | 78.00 | 21.21 | 39.27 |
| UniT | 67.72 | 75.75 | 61.69 | 70.92 | 5.19 | 44.59 | 6.36 | 46.06 |
| VITRA | 63.49 | 76.46 | 59.31 | 74.82 | 40.00 | 71.41 | 39.70 | 74.18 |
| RLDX-1 | 57.67 | 71.96 | 53.68 | 68.36 | 6.67 | 40.44 | 6.06 | 39.82 |
| GR00T-N1.7 | 55.56 | 70.46 | 55.63 | 69.05 | 0.74 | 37.19 | 1.82 | 40.58 |
| H-RDT | 51.85 | 67.11 | 34.85 | 53.21 | 14.81 | 54.26 | 9.09 | 46.18 |
| π0.5 | 46.56 | 62.70 | 34.20 | 51.01 | 19.26 | 49.59 | 16.06 | 46.29 |
| StarVLA | 43.39 | 54.76 | 40.48 | 51.77 | 17.04 | 52.67 | 16.97 | 51.80 |
| RDT-1B | 32.28 | 51.76 | 34.20 | 51.26 | 10.37 | 51.30 | 10.91 | 52.55 |
| Spark-0 | 80.95 | 88.18 | 75.97 | 83.80 | 68.15 | 80.96 | 61.82 | 80.53 |
SparkArena-Real Results
With online touch, Spark-0 reaches 52.00% success and a 62.80 completion score, 16.00 and 15.00 points above the strongest baseline, the tactile foundation policy FTP-1. Vision-only baselines often start the right behavior but rarely complete the contact sequence.
Success rate (%) / completion score. Highlight: best; bold: second.
| Method | Insert Test Tubes |
Pack Shoes into Box |
Place the Phone |
Stack Bowls |
Stand Up Bottle |
Mean |
|---|---|---|---|---|---|---|
| H-RDT | 0.000.00 | 0.000.00 | 0.000.00 | 0.000.00 | 0.000.00 | 0.000.00 |
| RDT-1B | 0.000.00 | 0.000.00 | 0.000.00 | 0.000.00 | 0.000.00 | 0.000.00 |
| π0.5 | 0.008.00 | 10.0050.00 | 0.0015.00 | 50.0073.00 | 10.0010.00 | 14.0031.20 |
| GR00T-N1.7 | 0.007.00 | 10.0030.00 | 0.0012.00 | 20.0051.00 | 50.0050.00 | 16.0030.00 |
| X-VLA | 0.0017.00 | 10.0010.00 | 10.0010.00 | 30.0054.00 | 60.0060.00 | 22.0030.20 |
| StarVLA | 0.000.00 | 30.0055.00 | 10.0010.00 | 20.0043.00 | 30.0030.00 | 18.0027.60 |
| FTP-1 | 0.0024.00 | 80.0080.00 | 20.0032.00 | 30.0053.00 | 50.0050.00 | 36.0047.80 |
| Spark-0 | 0.0031.00 | 80.0085.00 | 50.0056.00 | 50.0062.00 | 80.0080.00 | 52.0062.80 |
Playback is at 4× speed.
Insert Test Tubes
Pack Shoes into Box
Place the Phone
Stack Bowls
Stand Up Bottle
Pretraining and Tactile-Scale Analysis
Four variants differ only in pretraining. Scratch starts from Qwen3-VL. Visual PT uses the 1000H pretraining data with all touch discarded. 100H and 1000H retain touch for 100 and 1,000 hours of HumanTouch. The pretrained variants share RGB data and compute, so Scratch → Visual PT measures visual pretraining and Visual PT → 1000H measures tactile pretraining.
Mean success rate / score (completion on SparkArena, PSR on Ego Humanoid).
| Configuration | SparkArena-Sim | Ego Humanoid | SparkArena-Real |
|---|---|---|---|
| Scratch | 31.7135.17 | 58.3473.71 | 38.0051.80 |
| Visual PT | 36.5739.84 | 52.4569.89 | 44.0061.80 |
| 100H | 35.1438.01 | 59.4276.72 | 40.0052.00 |
| 1000H | 36.8639.74 | 71.7283.37 | 52.0062.80 |
Key findings
Visual pretraining helps where the embodiment is already seen.
Scratch already beats the strongest baseline on both SparkArena tracks. Scratch → Visual PT lifts Sim (+4.86) and Real (+6.00) but lowers Ego Humanoid from 58.34% to 52.45%.
Touch drives transfer to an unseen embodiment.
On identical RGB data, Visual PT → 1000H barely changes Sim (+0.29) but lifts Ego Humanoid by 19.27 points with no touch at test time. On Real, where every variant is deployed with touch, success rises from 44.00% to 52.00%.
The benefit is clearest at full scale.
Ego Humanoid rises with hours of touch (52.45 → 59.42 → 71.72). On Sim and Real, 100H does not exceed Visual PT; only 1000H attains the best success rate on all three.